PDF to Text Converter Online Free
Extract clean, editable text from native and scanned PDF files online with on-device OCR. Copy text or download as a .txt file with no page limits.
How to convert a PDF to text
Add your PDFs
Drop your PDFs in the box at the top of this page, or click to choose them. You can add up to 20 at once.
Let the pages be read
Pages with real text are read right away. Scanned pages are found for you and read with OCR in the language you pick. There's no mode to switch.
Copy or download
Edit the text if you like, then copy it or save it as a .txt file. With several PDFs, download everything as one .txt file or as a ZIP.
Key features
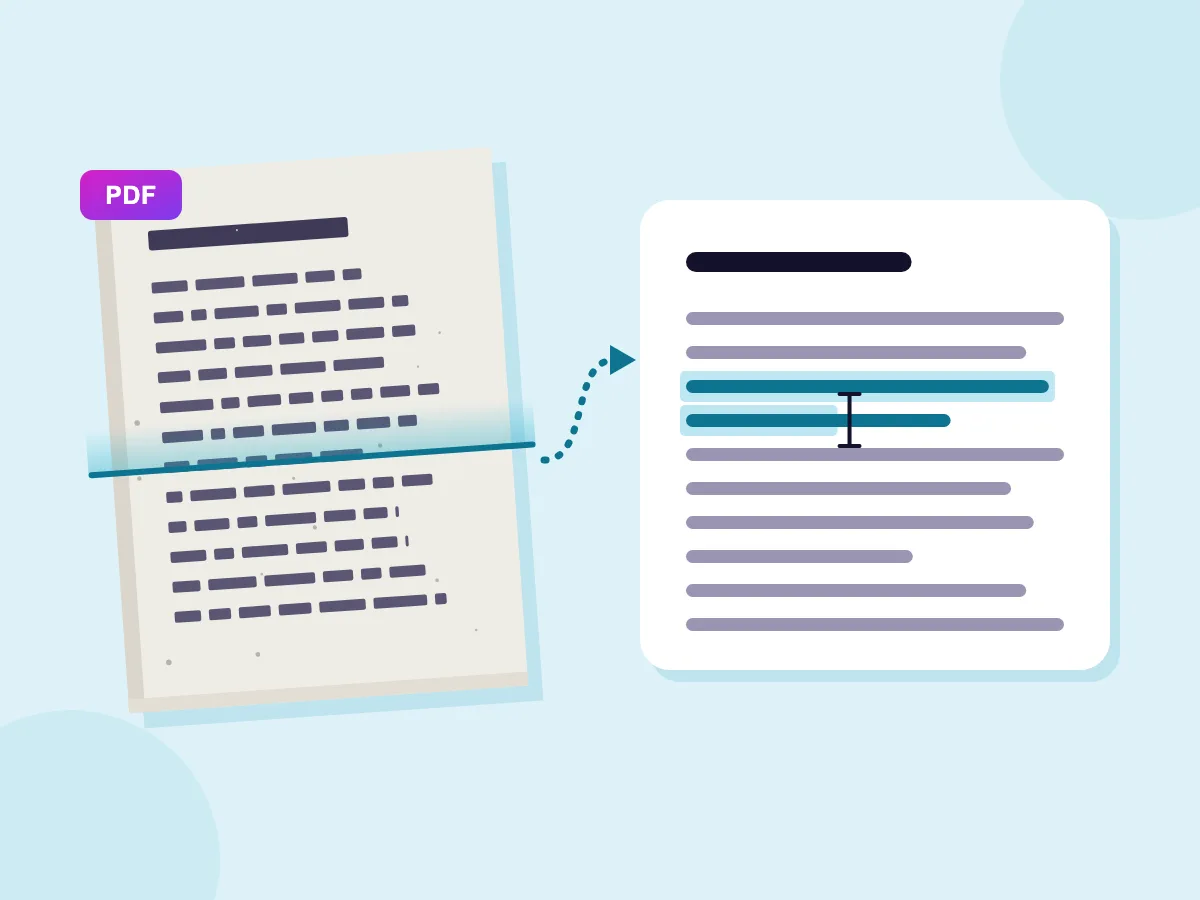
Reads scanned pages (OCR)
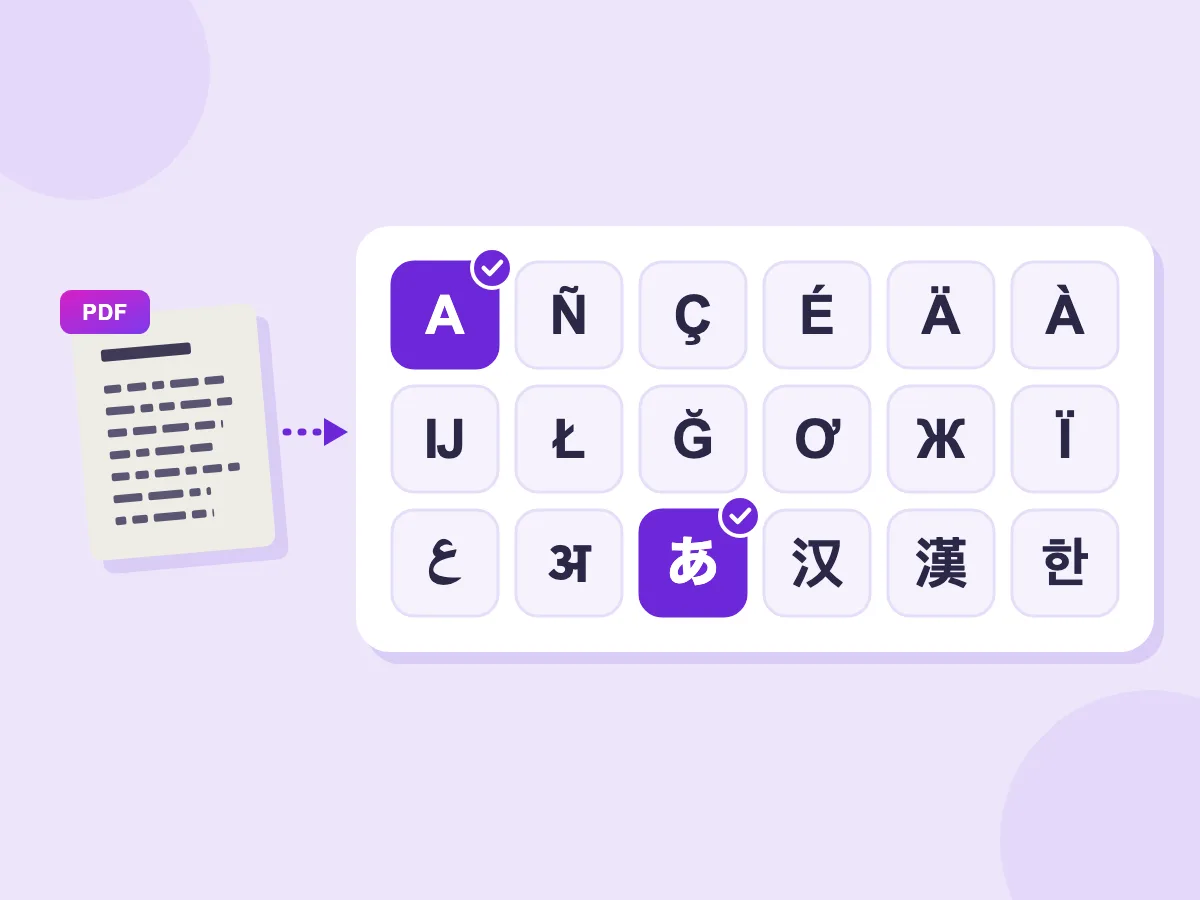
18 OCR languages
- Clean paragraphs
- Up to 20 PDFs at once
- Copy or save as .txt
What people use PDF to text for
Work
- Copy clauses from a contract or a scanned letter
- Reuse text from a report or slide deck saved as a PDF
- Get the details from an invoice or bank statement
- Paste the text into a document or spreadsheet app to edit it
School and research
- Quote a research paper without retyping it
- Turn scanned book pages into notes you can search
- Get the text out of lecture slides and handouts
- Collect quotes from several PDFs in one go
Everyday
- Paste a PDF into AI chat tools to summarize it or ask questions
- Copy text from a PDF that won't let you select it
- Paste the text into a translator
- Save a manual, form or recipe as a plain text file
Why can't I copy text from some PDFs?
Some PDFs hold a picture of the text instead of the text itself. A scanned page is just an image, so there is nothing to select or copy. This converter reads real text straight from the PDF with no OCR, which is fast and exact. It runs OCR only on the pages that are pictures.
Convert scanned PDFs to text with OCR
A scanned PDF is a picture of each page, so its text has to be read with OCR (optical character recognition). This converter checks every page on its own and reads the scanned ones with OCR automatically.
- Each page is marked as text, OCR or blank, so you can see which pages were scanned.
- Pages whose text copies out as boxes or odd symbols are treated as scans and read with OCR too.
- Scanned pages are read in the language you choose. Pick from 18 languages, up to 3 at once.
- If a page's text looks wrong, click its page number and choose Read with OCR to read it again as a scan.
Mixed PDFs work too. Typed pages and scanned pages come back together as one text, in page order.
Have a photo or screenshot instead of a PDF? Get its text with the image to text converter.
Copy text from a PDF without line breaks
Text copied from a PDF usually breaks at the end of every line. Join lines into paragraphs puts wrapped sentences back together, so the text pastes cleanly into a document, an email or AI chat tools. It's on by default.
The cleanup also fixes the other things that make PDF text messy:
- Words split with a hyphen at the end of a line are joined back into one word.
- Headings, list items and table rows stay on their own lines.
- Remove headers, footers and page numbers drops the running headers, footers and page numbers that repeat across the pages. It's on by default.
- Page markers such as --- Page 3 --- show where each page starts. Turn them off for one clean block of text.
Each option updates the text at once, with no need to read the PDF again. Turn Join lines into paragraphs off to keep every line break as it is in the PDF.
Free, private and unlimited
This PDF to text converter is free, with no sign-up and no account. You also get:
- Privacy. Your PDF stays on your device. It's opened and read right on your phone or computer, and the file is never sent to a server.
- No page cap and no daily cap. Each PDF can be up to 100 MB, and you can add up to 20 at a time.
- Locked files handled with care. A password-protected PDF is opened with your password on your device, and the password isn't saved.
The first time a scanned page is read, the OCR reader downloads once (about 4 MB with English). It's saved in your browser, so later scans start faster. PDFs with only real text don't need it.
What is the best way to extract text from a PDF?
Read the text the PDF already holds, and use OCR only on the scanned pages, in the right language. That keeps typed pages exact and scanned pages as accurate as possible. This tool makes that choice for you, page by page.
These tips give you cleaner text:
- Pick the right OCR language. German read as English loses its umlauts, for example.
- Choose up to 3 languages for scans that mix languages.
- Use a clear, straight scan. Faint or crooked pages give more mistakes.
- If a page comes out garbled, click its page number and choose Read with OCR.
- Check names, numbers and email addresses on scanned pages. They are the easiest to misread.
How long does it take to OCR a PDF? Pages with real text are read almost instantly, even in a long PDF. Each scanned page takes a few seconds, and you can watch the progress or stop at any time.
OCR is made for printed text. Handwriting and poor scans often come out with mistakes. Complex layouts like magazines and forms can also come out in a mixed-up order, so read the text through before you use it.
Frequently asked questions
Scanned pages, languages, limits and privacy
How do I convert a PDF to text for free?
Add your PDF to the box at the top of this page, and the text appears as each page is read. Then copy it or download it as a .txt file. It's free, with no sign-up and no daily limit.
Can I extract text from a scanned PDF?
Yes. Pages with no real text are found automatically and read with OCR, in the language you pick. Clear, printed scans give the most accurate text. Faint copies and handwriting cause more mistakes, so check names and numbers.
Is my PDF uploaded to a server?
No. Your PDF is opened and read on your own device, and the file and its text stay there. The tool downloads an OCR language model the first time it reads a scanned page, but nothing from your PDF is sent.
Can I extract text from a password-protected PDF?
Yes, if you know the password. Type it when asked, and the PDF is opened on your device. The tool doesn't remove or crack passwords, and your password isn't saved or sent anywhere.
Which languages can it read?
Pages with real text are read in the language the PDF stores. Scanned pages are read with OCR in 18 languages, including English, Spanish, French, German, Chinese, Japanese, Korean, Arabic, Hindi and Russian. Pick up to 3 at once for mixed text.
Will the formatting be preserved?
No. The result is plain text, so fonts, colors, images and exact layout aren't kept. Paragraphs, headings, list items and table rows do stay on their own lines. To keep the pages looking exactly the same, turn the pages into images instead.
Can I save the text as a TXT file?
Yes. Download .txt saves a UTF-8 text file named after your PDF, so accents and non-Latin letters show correctly. You can edit the text first; your edits are what gets saved.
Is there a page or file size limit?
There's no page limit and no daily limit. Each PDF can be up to 100 MB, and you can add up to 20 PDFs at a time. Long scanned PDFs take longer, because each scanned page is read one at a time.
Can I convert several PDFs at once?
Yes, up to 20 PDFs at a time. They're read one after another. Then copy all the text, download it as one .txt file with a heading for each PDF, or get a ZIP with one text file per PDF.
Does it work on a phone?
Yes. Open this page in your phone's browser on iPhone or Android, add a PDF, and copy the text. There's no app to install. Scanned pages take longer on a phone than on a computer.